
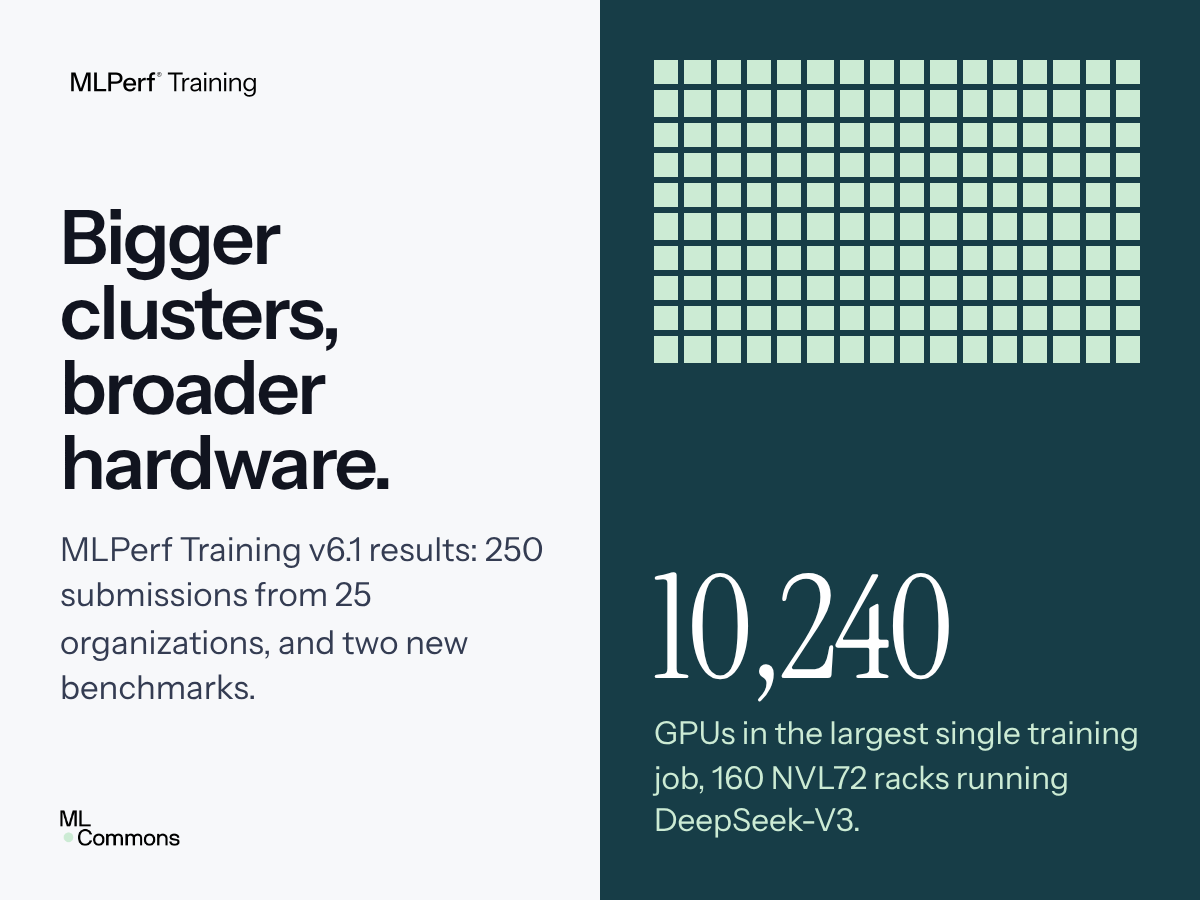
Round Overview
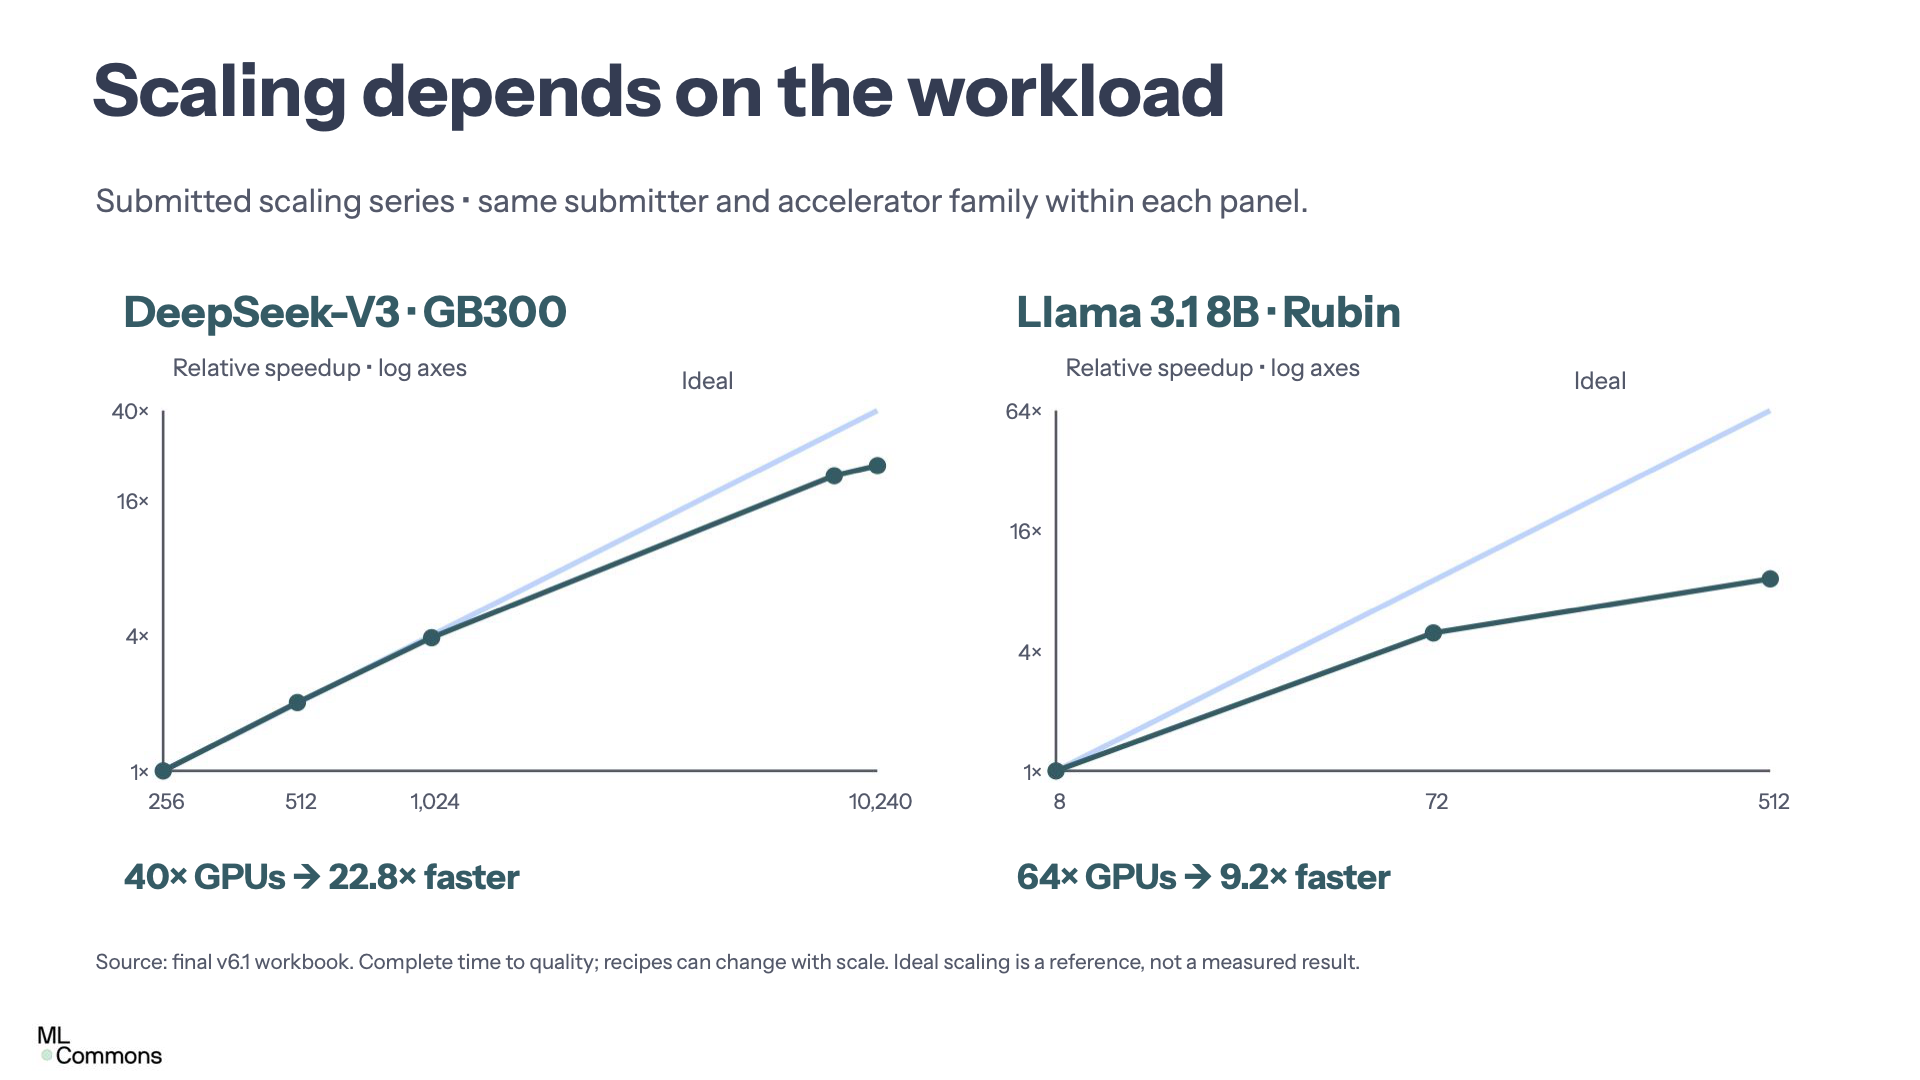
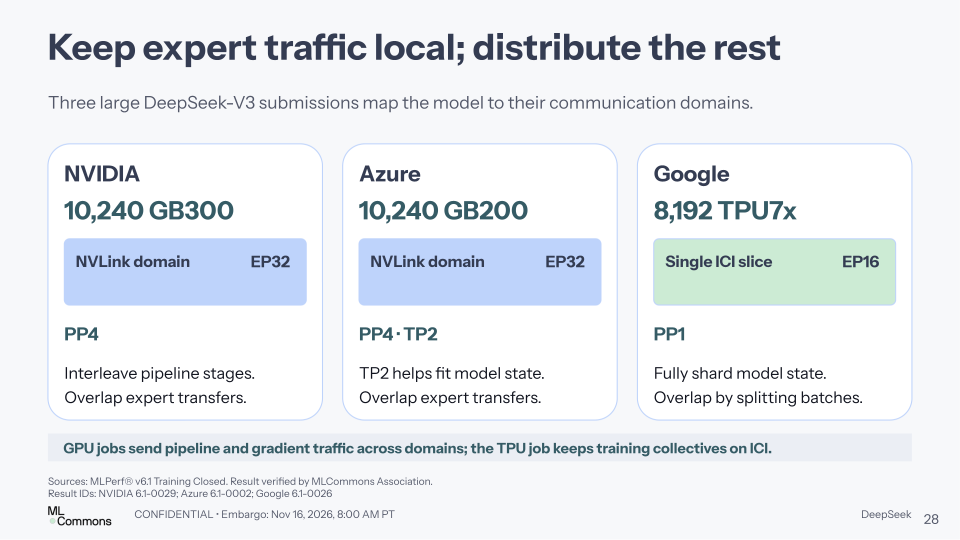
MLPerf Training v6.1 expands the benchmark suite and showcases larger-scale systems submitted by members. Two new benchmarks were added: Qwen3.5-397B GRPO for agentic reinforcement learning and DLRMv4-HSTU for generative recommendation models. Google Ironwood and NVIDIA Rubin made their debut as available systems. The largest job scale reached 10,240 GPUs (NVIDIA GB300 and Azure GB200, both training DeepSeek-V3), the share of multi-node systems rose to 76%, and the hardware mix expanded to 12 accelerators and four scale-out interconnect technologies.
This round received 250 submissions from 25 submitters, up from 229 in v6.0.
AI Training Performance Outpaces Moore's Law
The geometric mean growth rate of the MLPerf Training performance index far exceeds the Moore's Law assumption of doubling every two years. From v0.6 to v6.1, cumulative performance gains were significant, particularly on tasks such as FLUX.1.
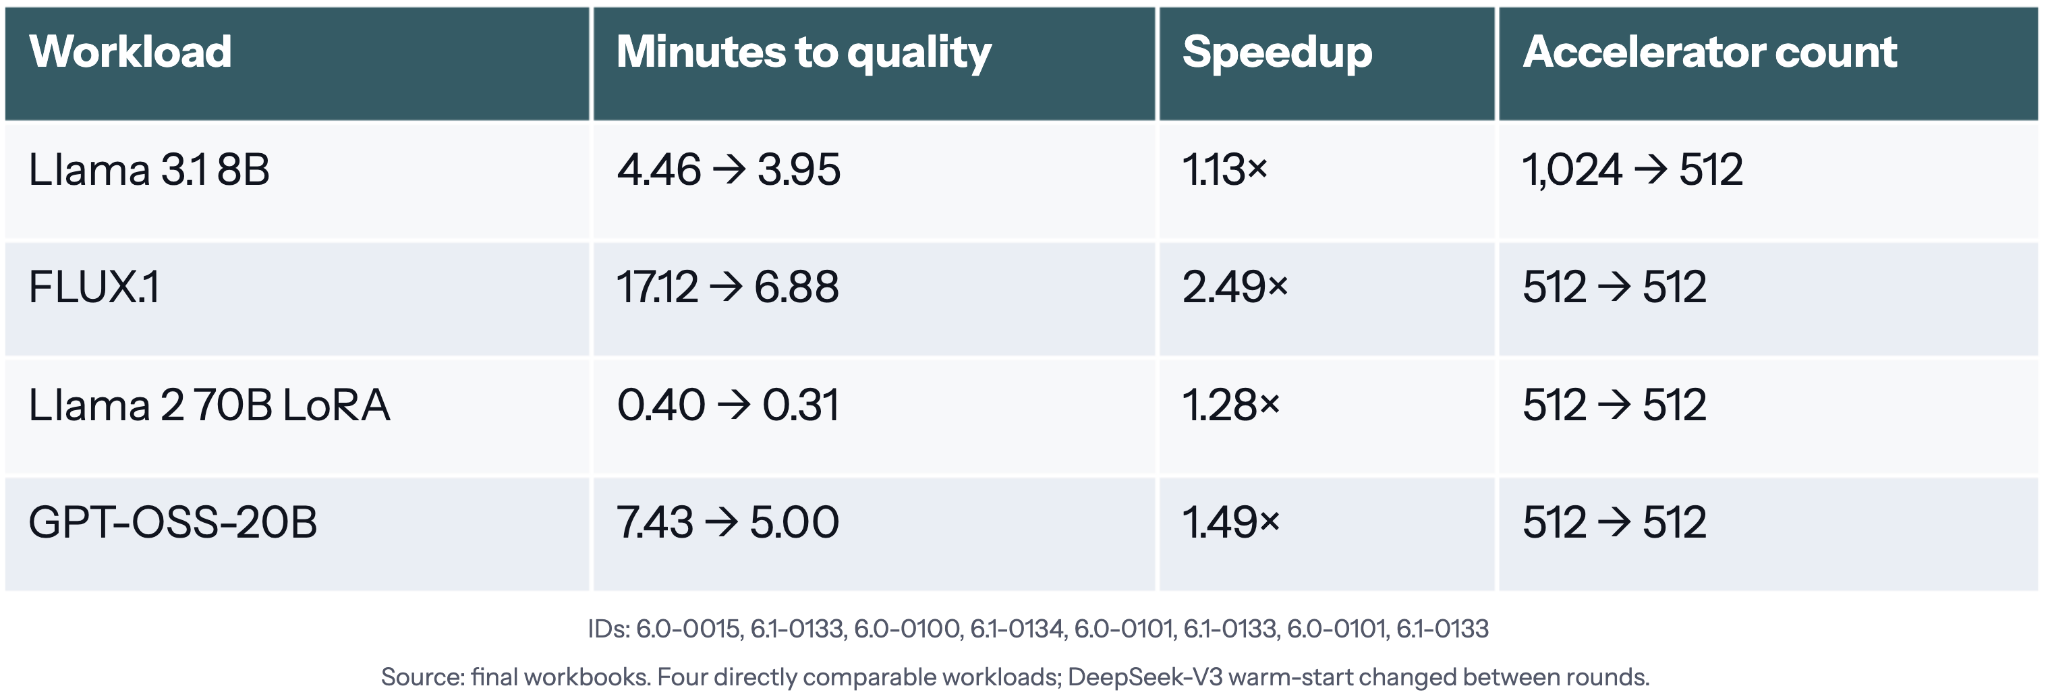
Comparable Benchmark Performance Comparison
Among the four continuing benchmarks, systems of the same scale (128 nodes, 512 accelerators) showed clear acceleration in v6.1, with FLUX.1 improving especially rapidly.
Benchmark Updates
Added Qwen3.5-397B GRPO (7 submitters, 29 results) and DLRMv4-HSTU (8 submitters, 20 results). At the same time, Llama 3.1 405B and DLRM-DCNv2 were retired, shifting toward MoE models and next-generation recommendation tasks.
Submitter Composition and Purposes
Chip vendors focused on first appearances of new silicon, server vendors demonstrated multiple configuration options, cloud service providers validated production-environment competitiveness, academic institutions completed submissions on shared clusters, and software optimization and power measurement also stood out.
Multi-Node Systems Become the Norm
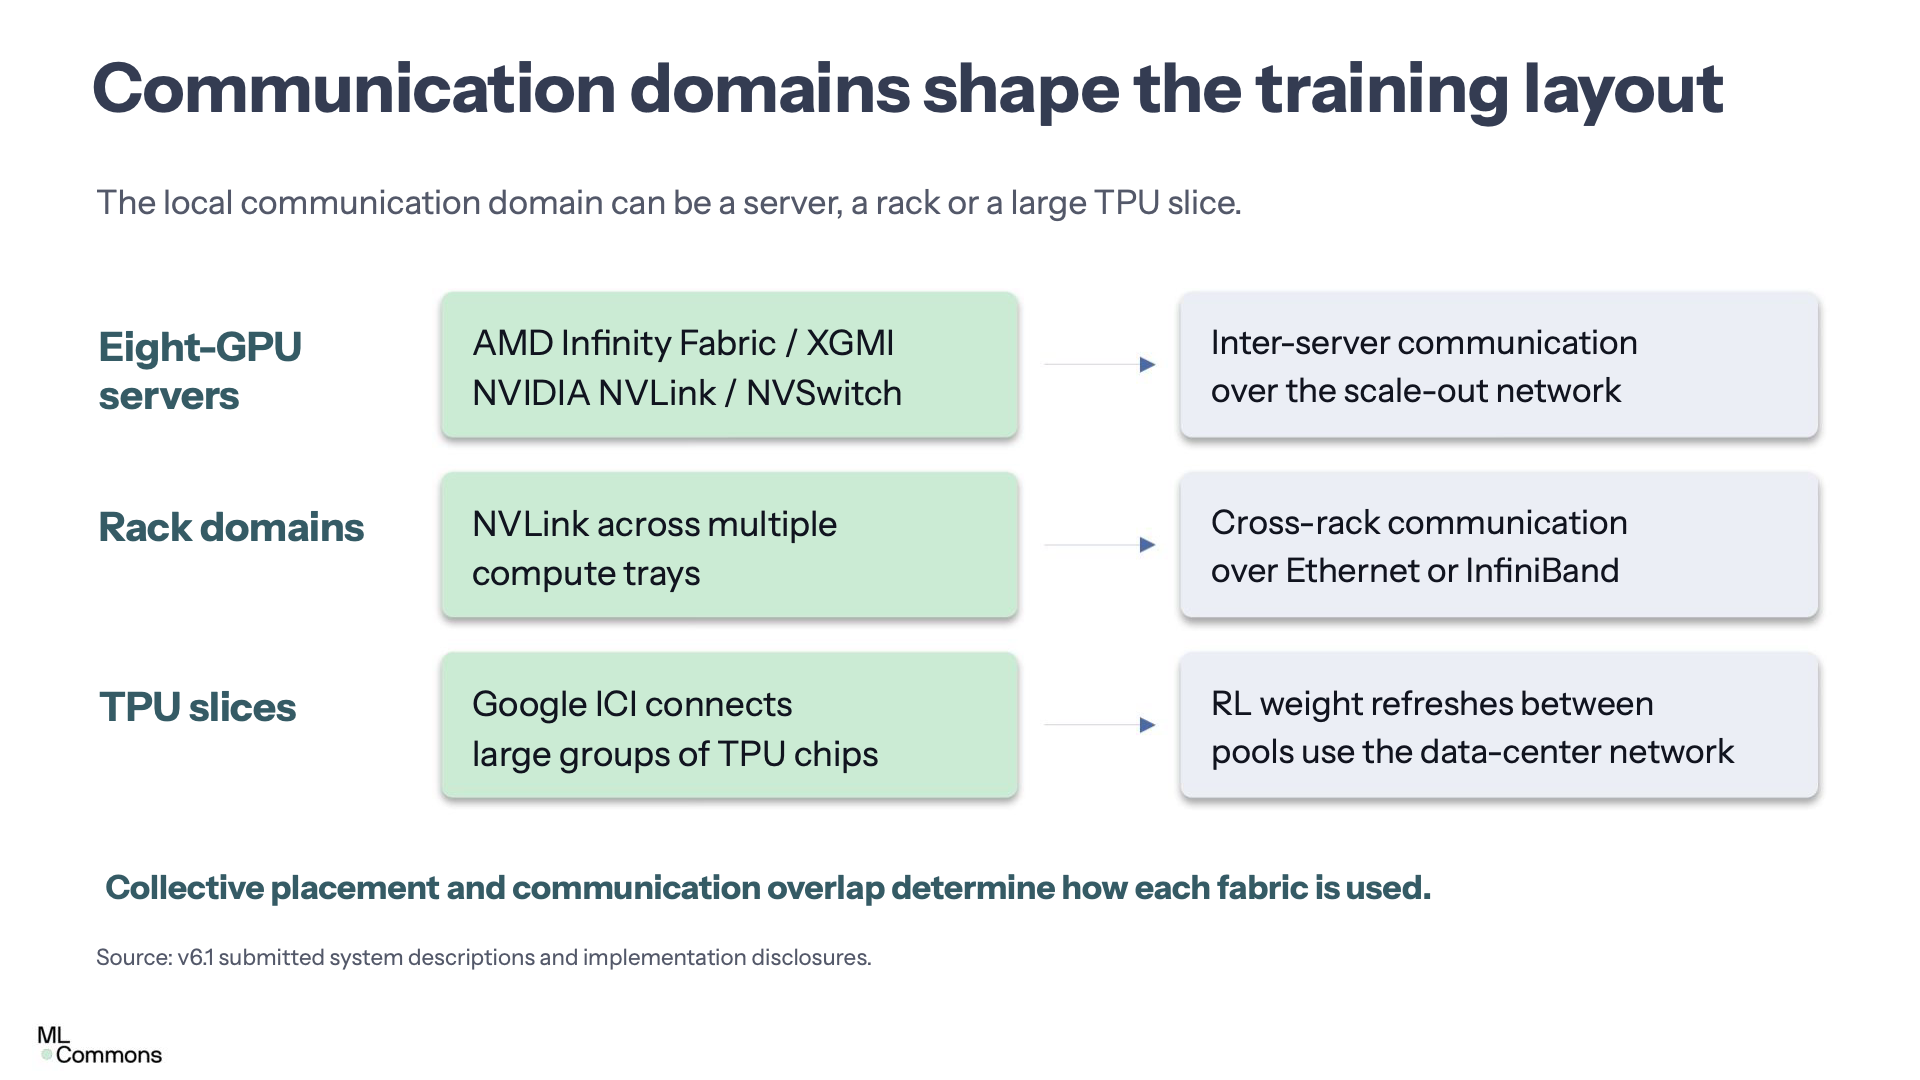
76% of systems used multiple nodes, with the largest reaching 10,240 GPUs. Node designs are evolving toward rack scale, with 4-accelerator nodes and 8-accelerator servers coexisting.
Accelerator Distribution
NVIDIA products accounted for 122 systems, while AMD and Google TPU7x contributed 27 and 4 systems respectively, as hardware diversity continued to expand.
© 2026 Winzheng.com 赢政天下 | 转载请注明来源并附原文链接