SGLang 为 Muse Spark Open 提供首日支持

SGLang 为 Muse Spark Open 提供首日支持

亮点概述

Muse Spark Open 是一款开放权重的多模态混合专家模型,采用 816B 参数的文本 Transformer 主干,每 token 激活参数约 42B,支持文本、图像、视频和音频输入,上下文窗口达 1M token。检查点提供 NVFP4 和 BF16 版本。

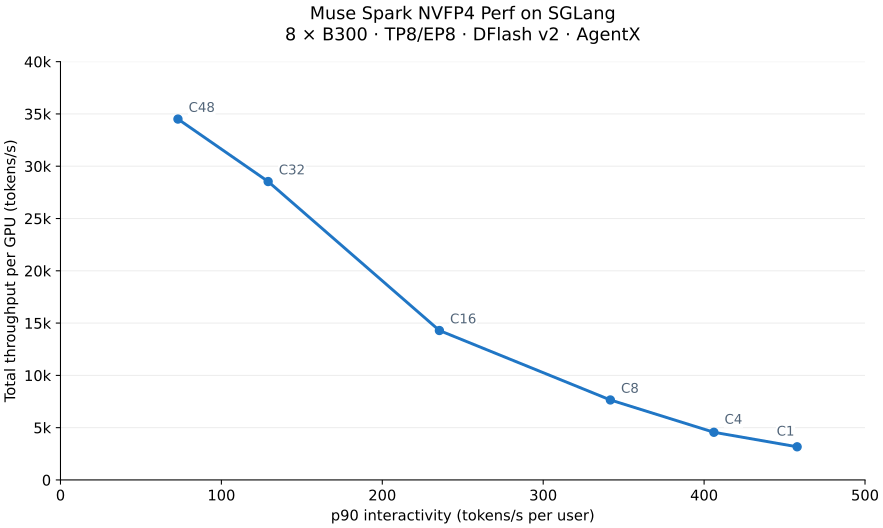
在 8 张 NVIDIA B300 GPU 上运行 NVFP4 检查点时,SGLang 可实现每 GPU 14.8K 总 tokens/sec(并发 1,p50 543 tokens/sec/用户)和 80.3K 总 tokens/sec(并发 128,p50 61 tokens/sec/用户)的性能。

Muse Spark Open 架构

Muse Spark Open 将稀疏语言解码器与视觉和音频编码器结合,把多模态输入统一送入共享的 token 生成流程。
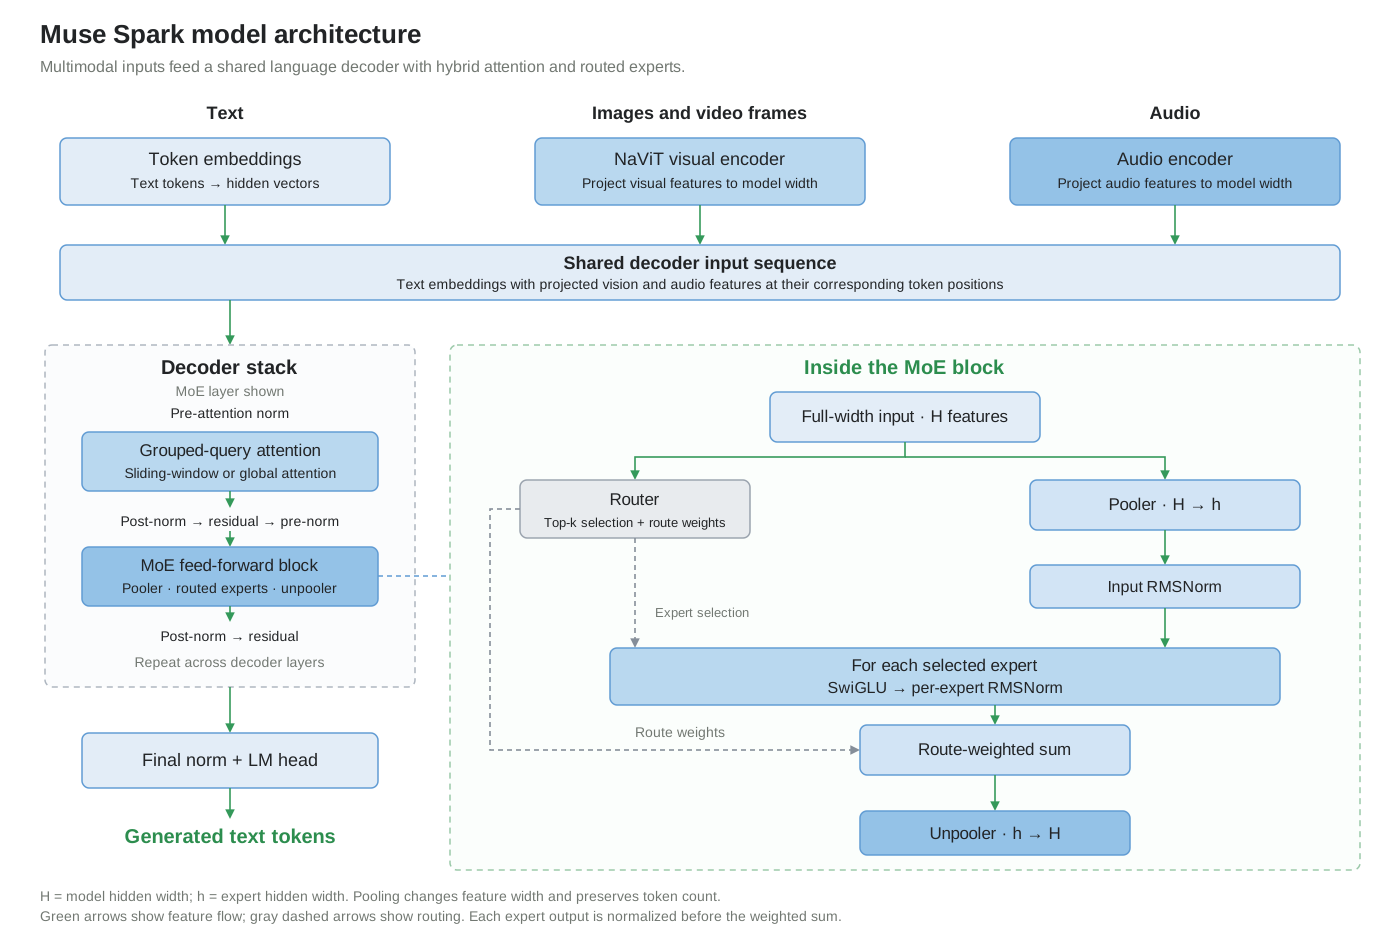
Muse Spark Open maps text, image/video and audio inputs into a shared decoder with GQA and sliding-window/global attention; its MoE block routes full-width inputs while pooling expert features, normalizing each expert output before the weighted sum and restoring the model width with an unpooler.

GQA 与滑动窗口注意力

为支持 1M token 上下文,模型结合分组查询注意力(GQA)与滑动窗口及全局注意力的混合机制。

文本、音频、图像与视频处理

图像和视频帧共享 NaViT 视觉编码器,波形音频通过专用音频编码器处理,输出投影至解码器隐藏维度。

带 Pooler/Unpooler 的 MoE 及每专家归一化

MoE 模块使用 pooler 和 unpooler 投影,并对每个专家输出执行 per-expert RMSNorm。
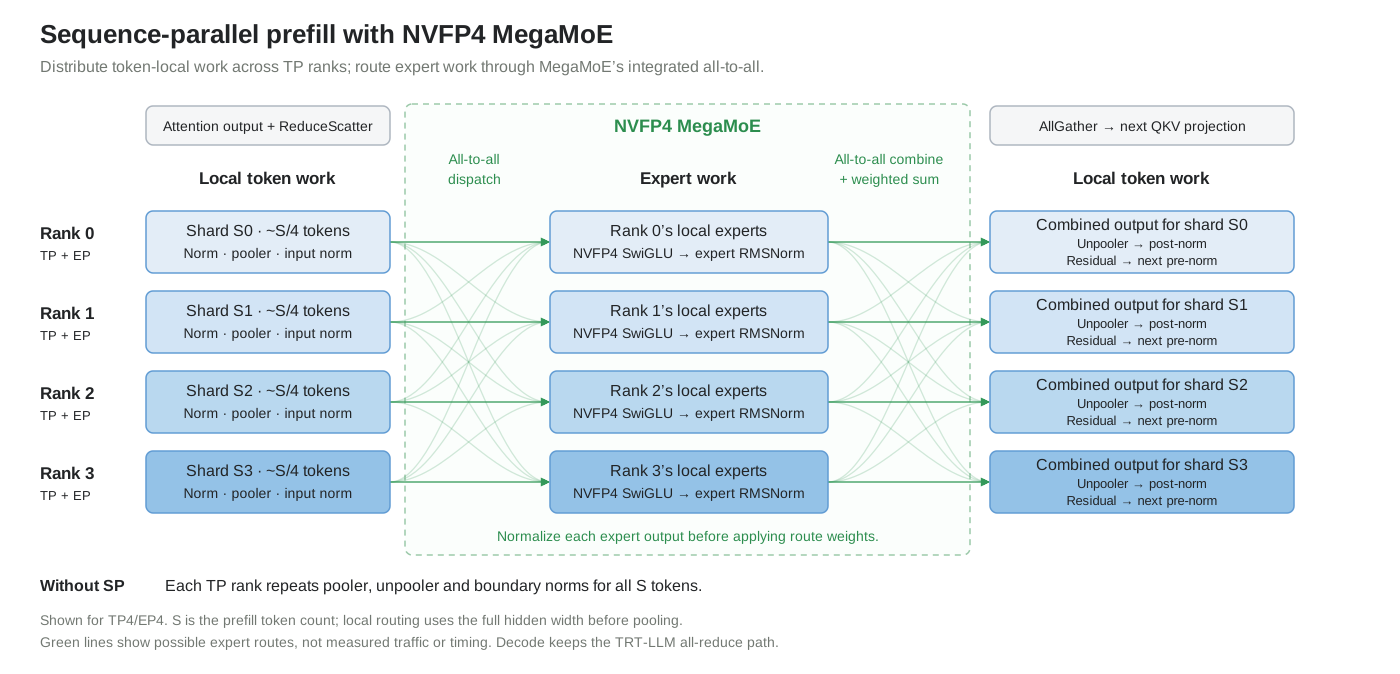
Four TP/EP ranks keep token shards, dispatch them to NVFP4 MegaMoE expert owners, and combine normalized expert outputs back to the original ranks before local unpooling.

运行时优化

序列并行

序列并行(SP)将激活沿 token 维度划分,结合 NVFP4 MegaMoE 实现更快的预填充。在四张 GB300 GPU 上的测试显示,SP + MegaMoE 将 p90 TTFT 降低 28.3–41.9%。
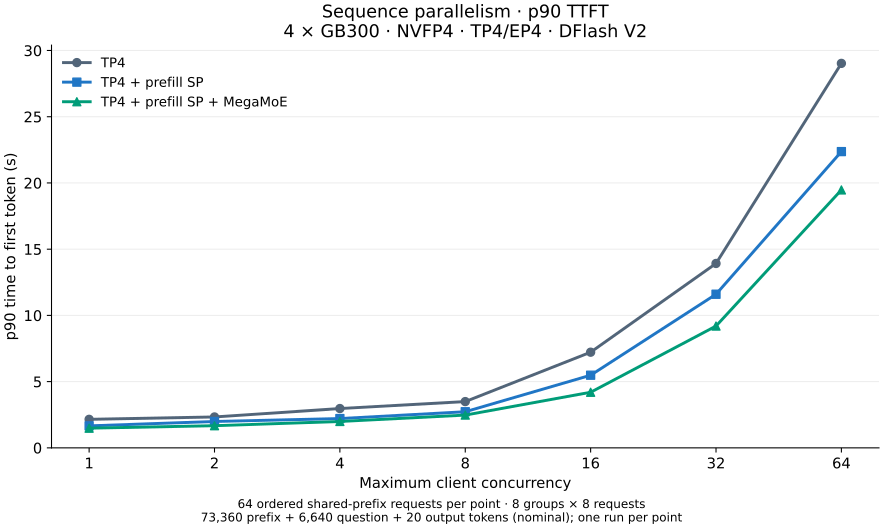
p90 TTFT for TP4, TP4 with prefill SP, and TP4 with prefill SP and MegaMoE across maximum concurrency 1 to 64 on four GB300 GPUs with DFlash V2.

多模态优化

支持 CPU 端 Rust/Pillow 图像预处理及 SGLang 优化注意力后端,并支持 EPD 解耦。

DFlash V2 推测解码

通过 DFlash V2 实现动态卷积和候选选择,支持块验证。
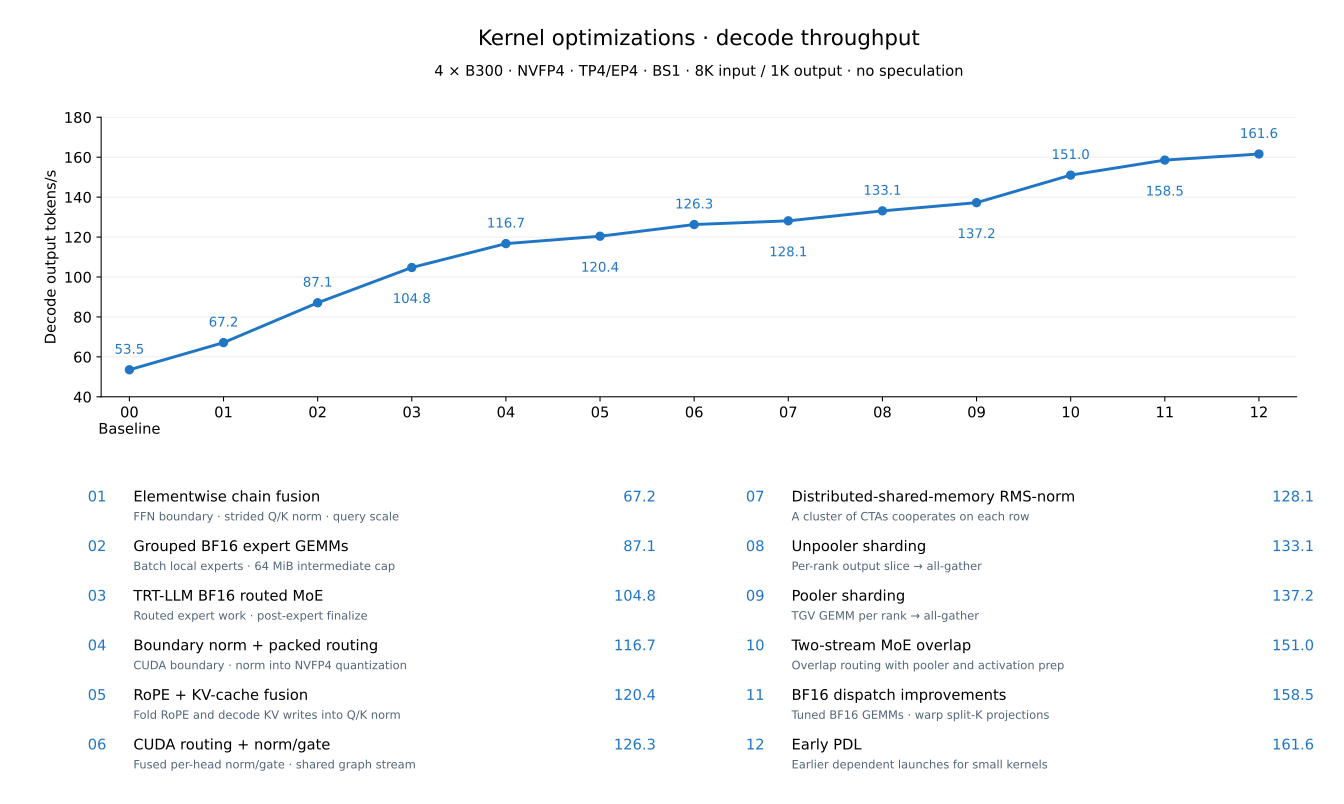
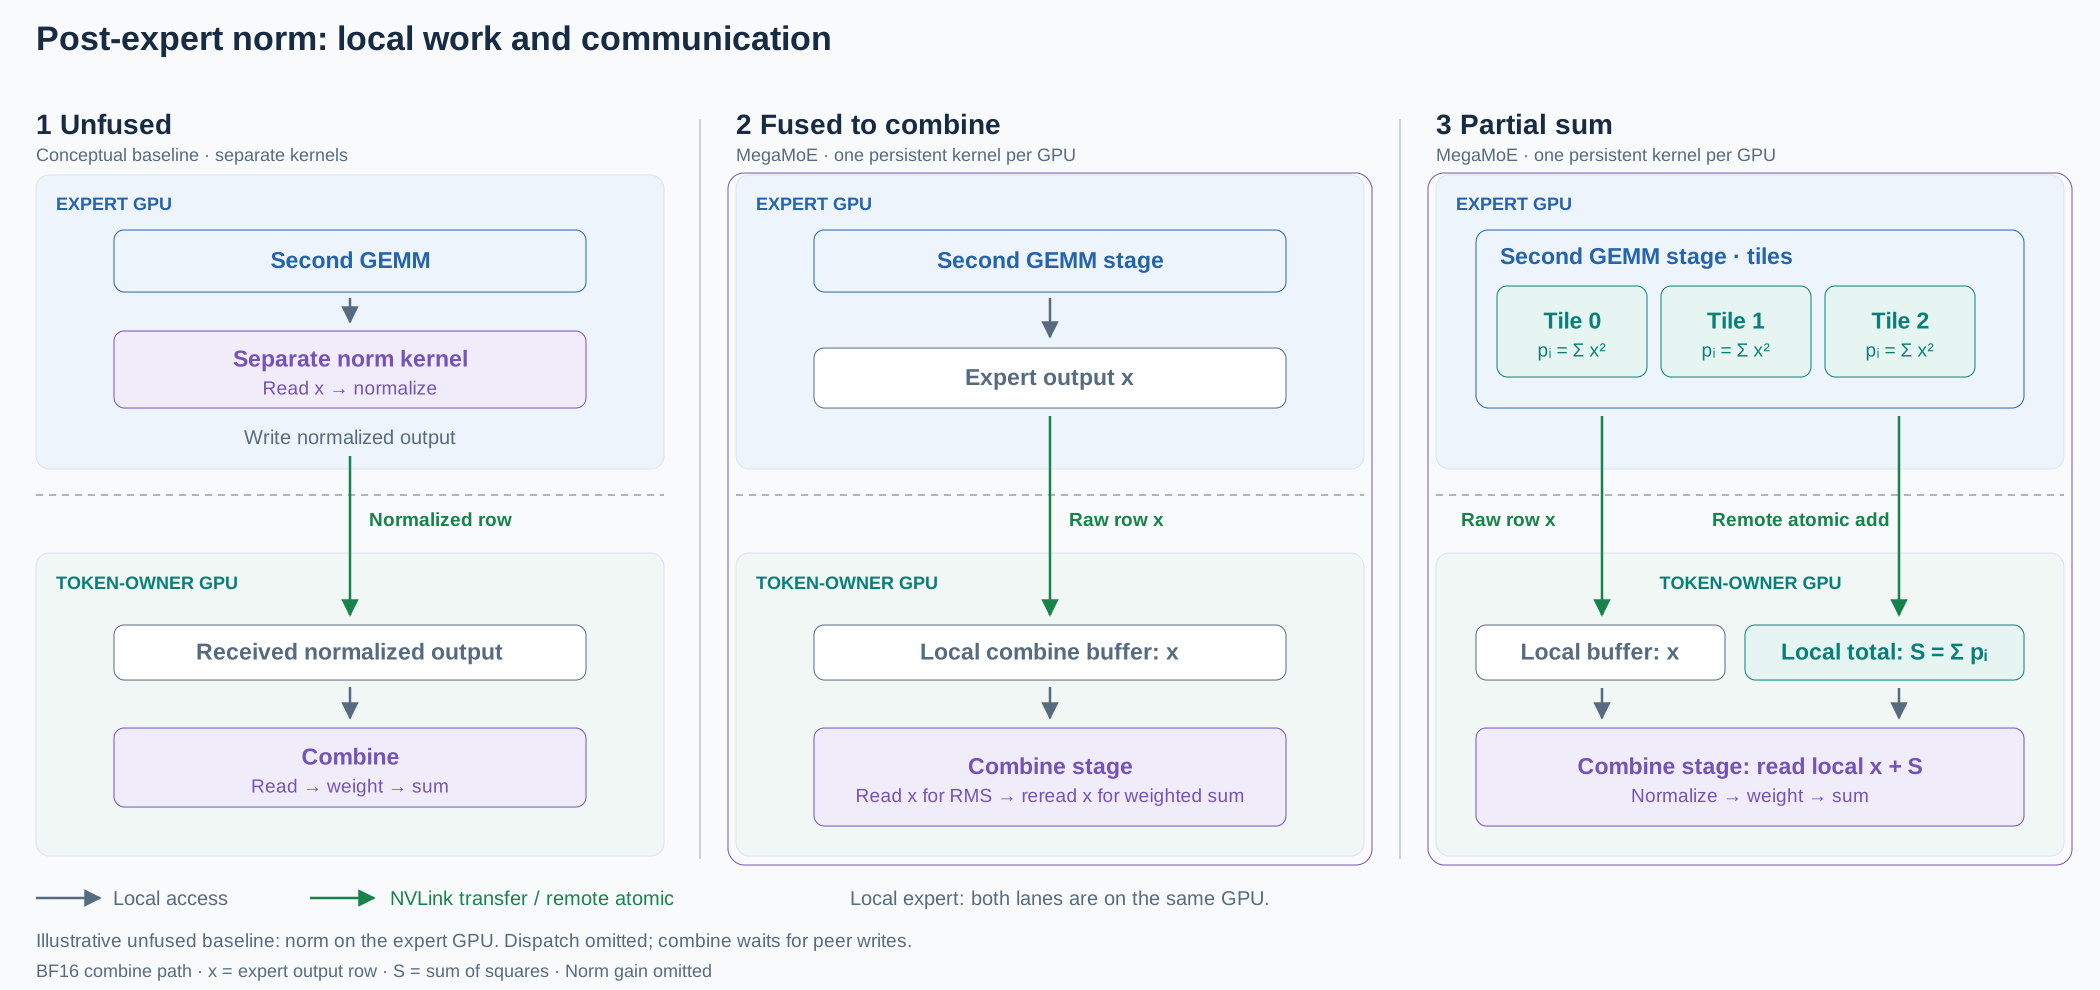
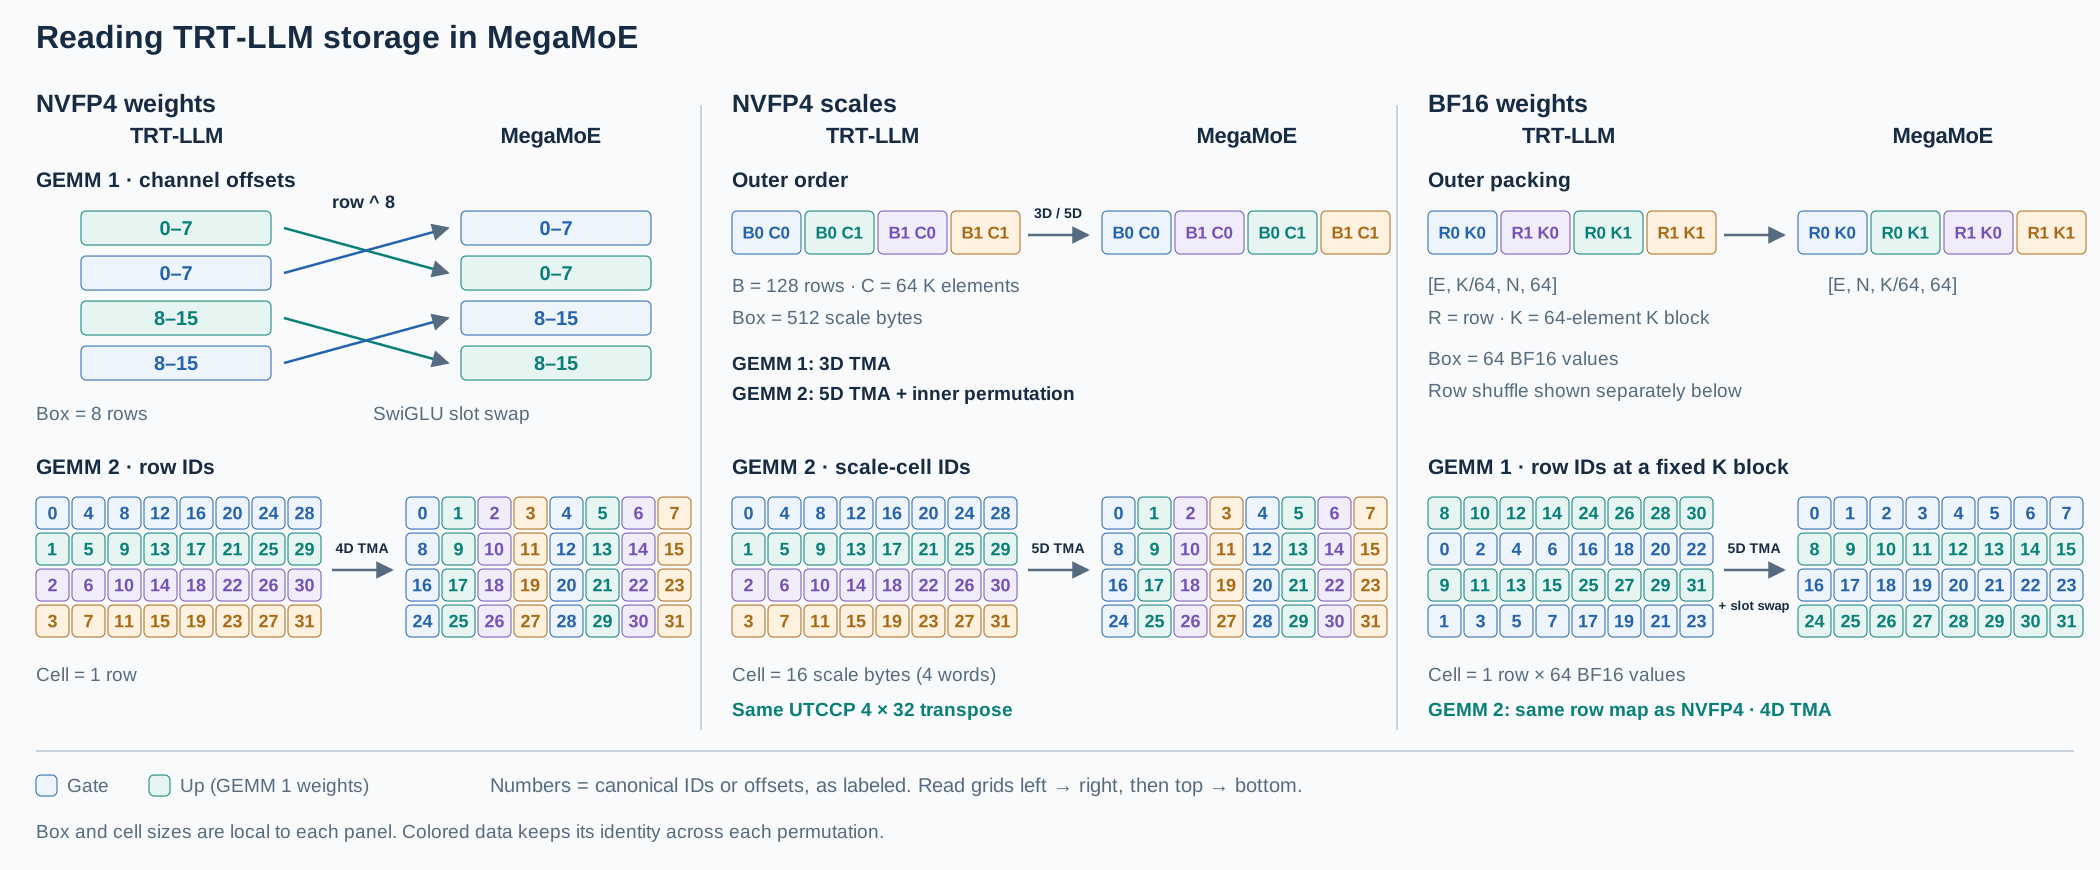
Cumulative kernel optimizations at BS1, TP4/EP4, 8K input and 1K output tokens, without speculative decodingPost Expert NormMegaMoE reads TRT-LLM layouts

内核优化与性能

通过减少内核启动、内存流量优化及重叠计算,显著提升吞吐。
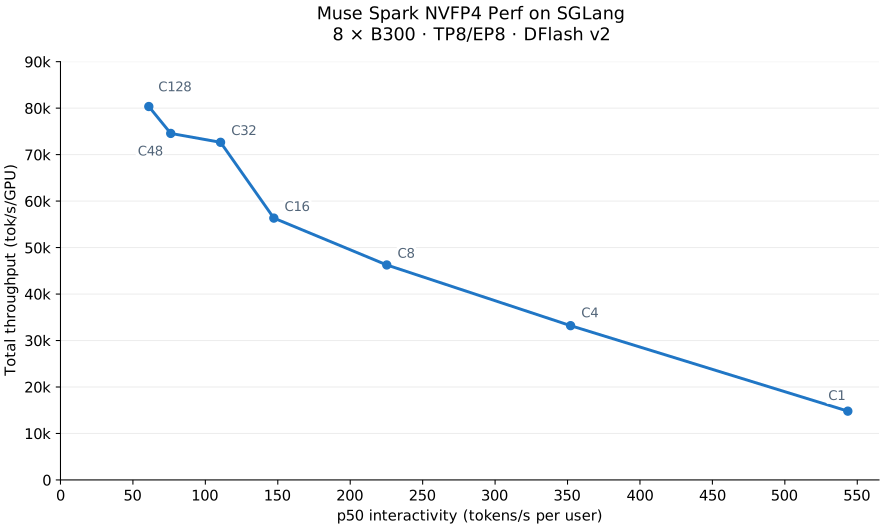
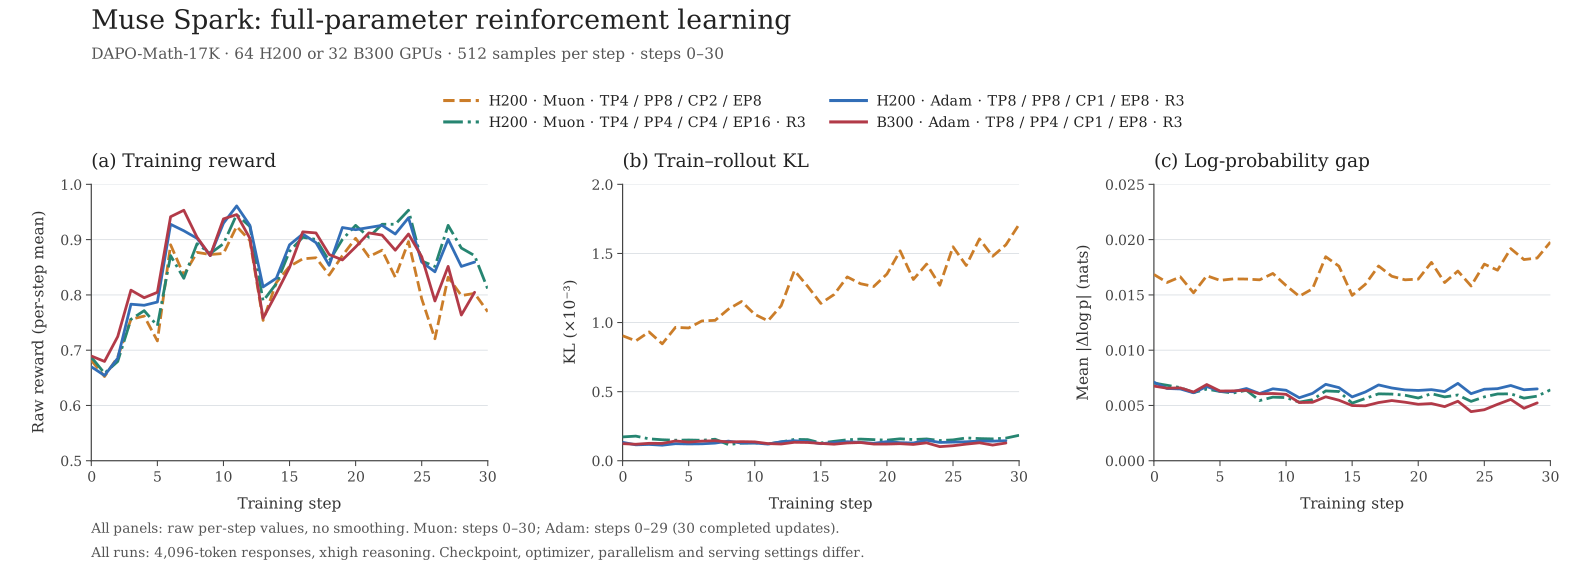
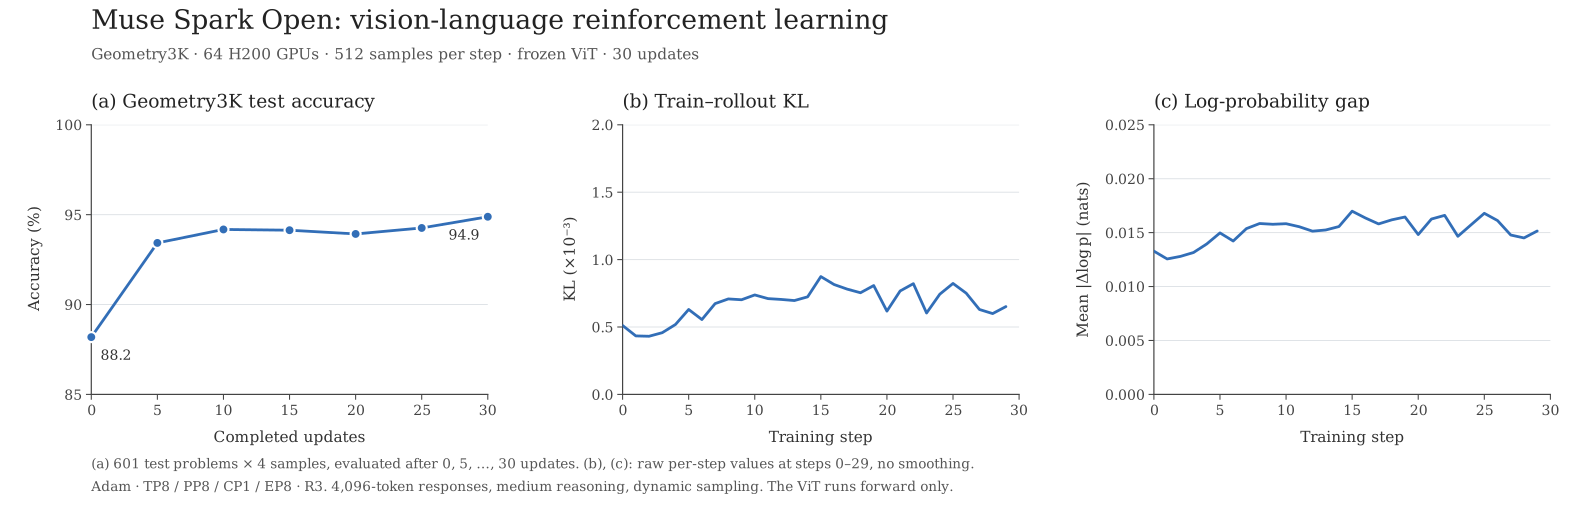
Muse Spark NVFP4 throughput per GPU versus p50 interactivity on eight B300 GPUs with DFlash v2.Muse Spark NVFP4 total throughput per GPU versus p90 interactivity on eight B300 GPUs with AgentX.Two Muon runs and two Adam runs, one of them on B300: unsmoothed training reward, train–rollout KL, and absolute log-probability difference. The legends identify each GPU type, training topology and whether rollout routing replay is enabled.Geometry3K RL with the ViT frozen: test accuracy after 0, 5, …, 30 updates, and per-step train–rollout KL and absolute log-probability difference.
本文来自 LMSYS 博客,赢政天下(winzheng.com)进行了全文翻译。 点击这里查看原文 如果转载中文,请注明出处,谢谢支持!