
概述
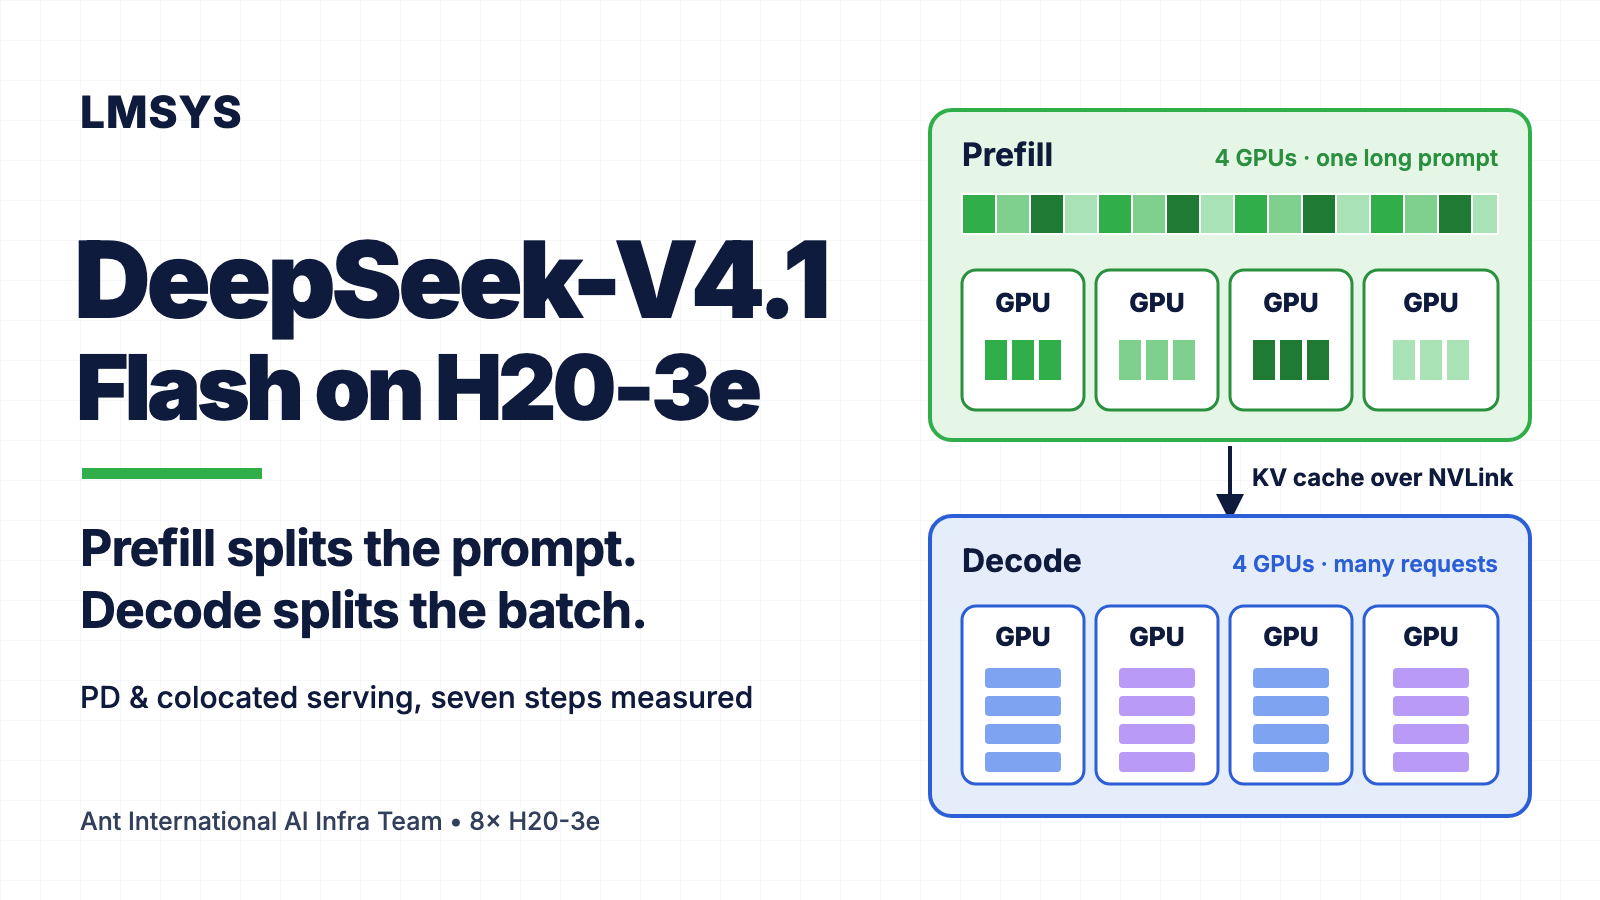
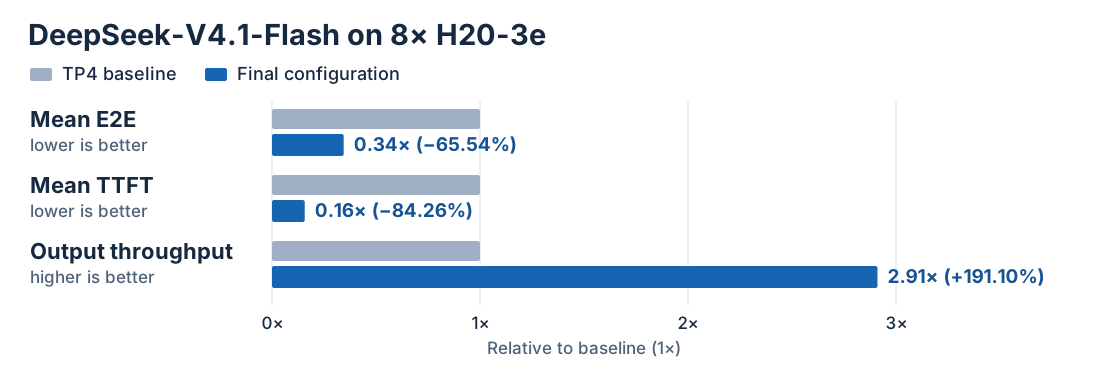
Ant International AI Infra 团队在 H20-3e 上优化了 DeepSeek-V4.1-Flash 的分离式服务。通过调整 prefill 与 decode 并行度、支持 BCG 配合 prefill CP 及有界 SWA 重放,并加速 Indexer 内核,最终配置相比 TP4 将平均端到端延迟降低 65.5%,输出吞吐提升 2.91 倍。
节点内 PD 部署中,prefill 和 decode 各使用 4 张 GPU,通过 NVLink 传输 KV cache。平均端到端延迟从 13.63s 降至 4.70s,输出吞吐从 847 tokens/s 提升至 2,465 tokens/s。
测量设置
路由器将请求分别发送至 prefill 和 decode 阶段,worker 通过 Mooncake NVLink 直接传输 KV 状态。基线在两个 worker 上均运行 TP4 attention 和 EP4 MoE,使用 eager BF16 Torch 进行 prefill scoring。
1. Prefill CP 与 Decode DP
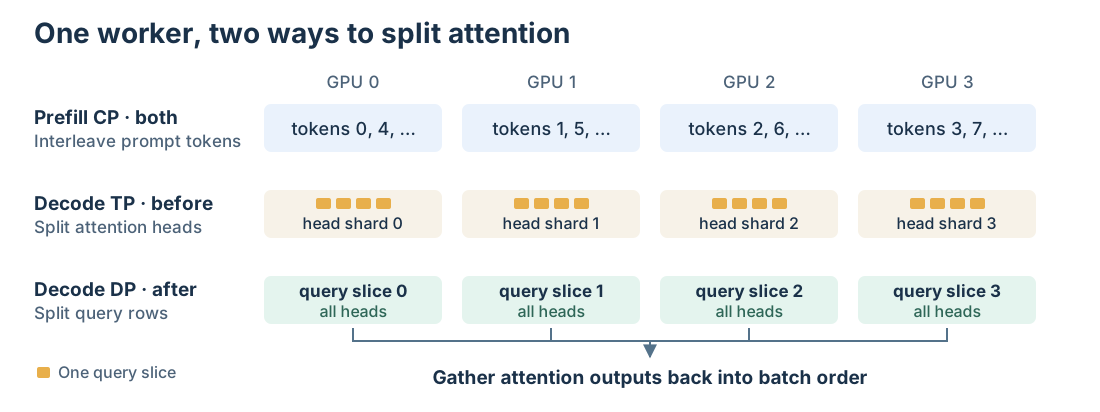
Prefill 使用交错上下文并行(Interleaved CP4),decode 则采用数据并行(DP4)attention 和 LM head。该步骤使平均 TTFT 从 12.04s 降至 5.16s。
2. FP8 DeepGEMM 用于 Prefill Indexer
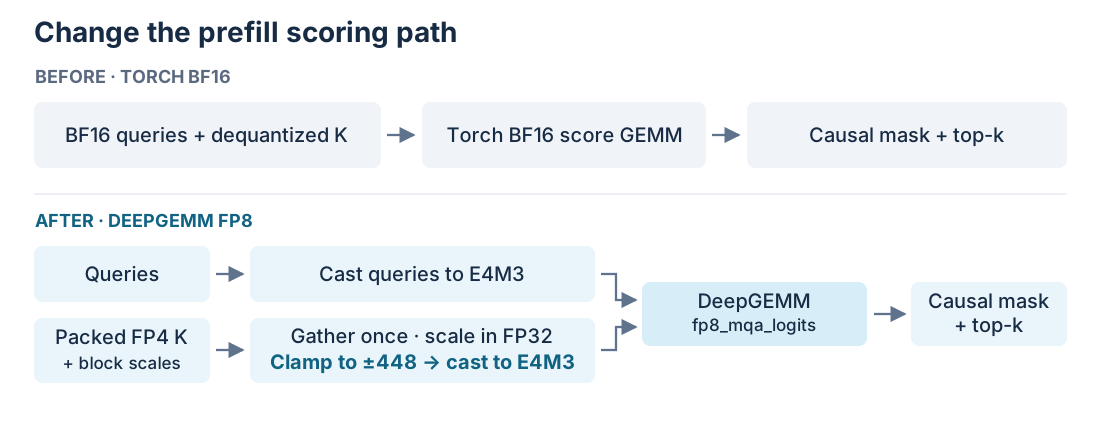
Indexer 在预填充阶段使用 DeepGEMM 的 fp8_mqa_logits 进行评分,键值经 FP4 缩放和裁剪后转为 E4M3。
3. Breakable CUDA Graphs 用于 Prefill
通过 Breakable CUDA Graphs 捕获图安全片段并重放,结合有界 SWA 重放,减少小内核启动开销。
4. Tensor-Parallel MoE
采用 TP MoE 将专家分片到所有 rank,避免 EP 下专家负载不均。
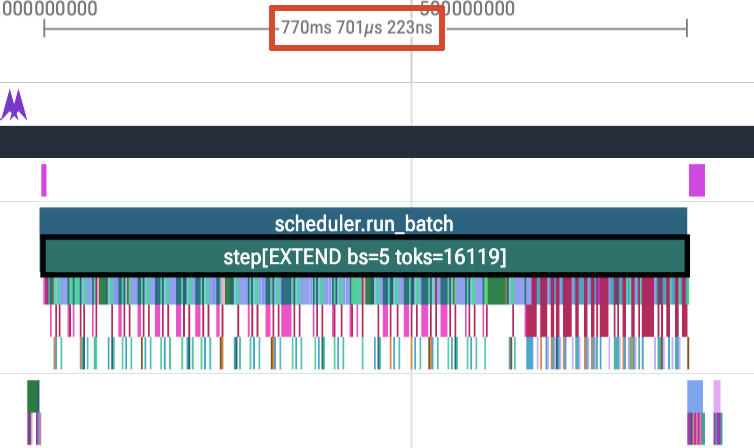
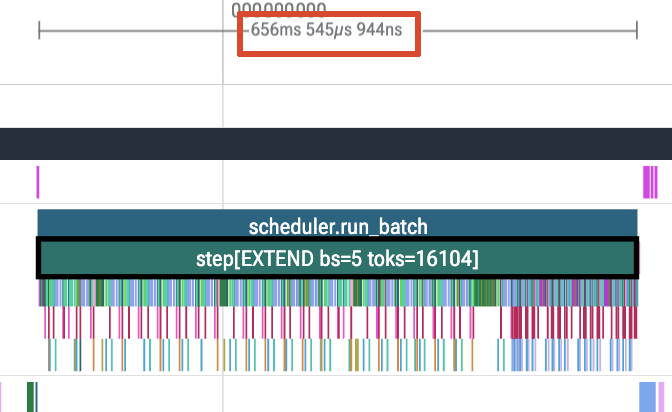
Prefill 时间线对比显示 TP 模式更快。
5-7. 其他优化
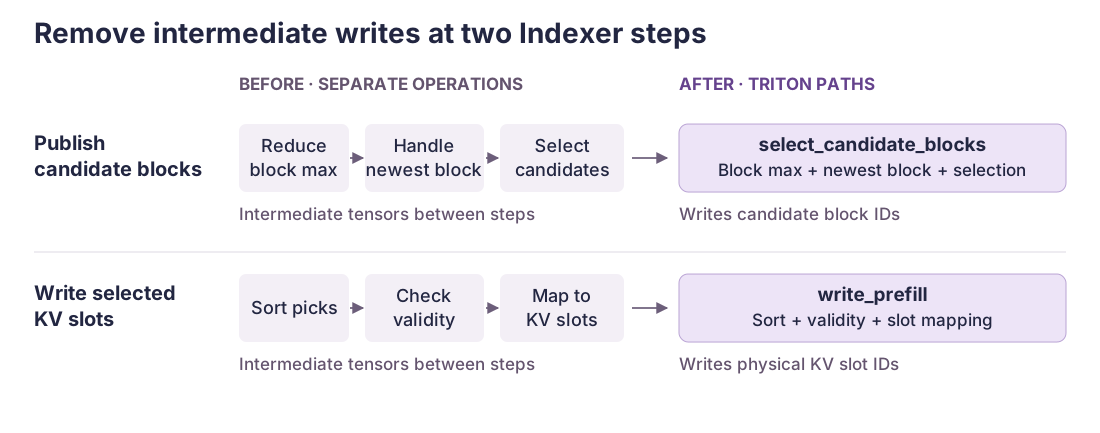
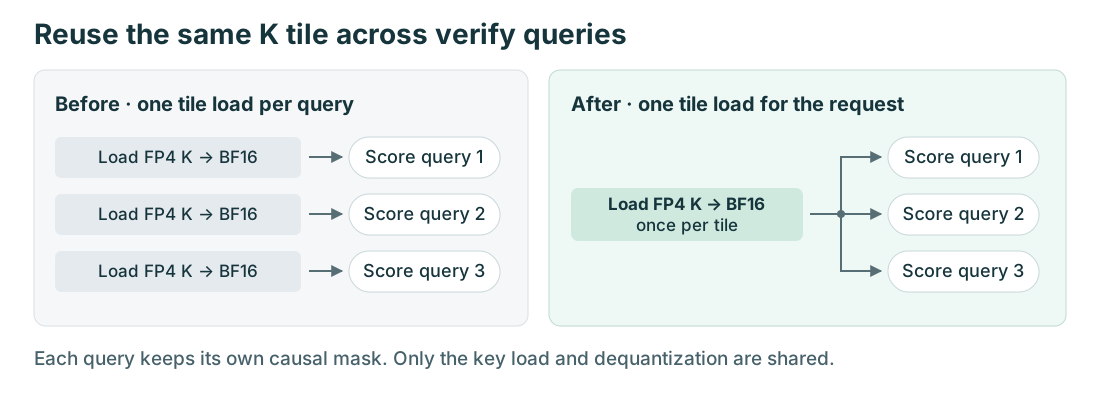
包括增大 Indexer score tile、融合 prefill selection 与 writeback 以及 paged K-tile 重用,进一步微调性能。
© 2026 Winzheng.com 赢政天下 | 转载请注明来源并附原文链接